VECTIQ
← Generative AI & Data

Document AI & OCR

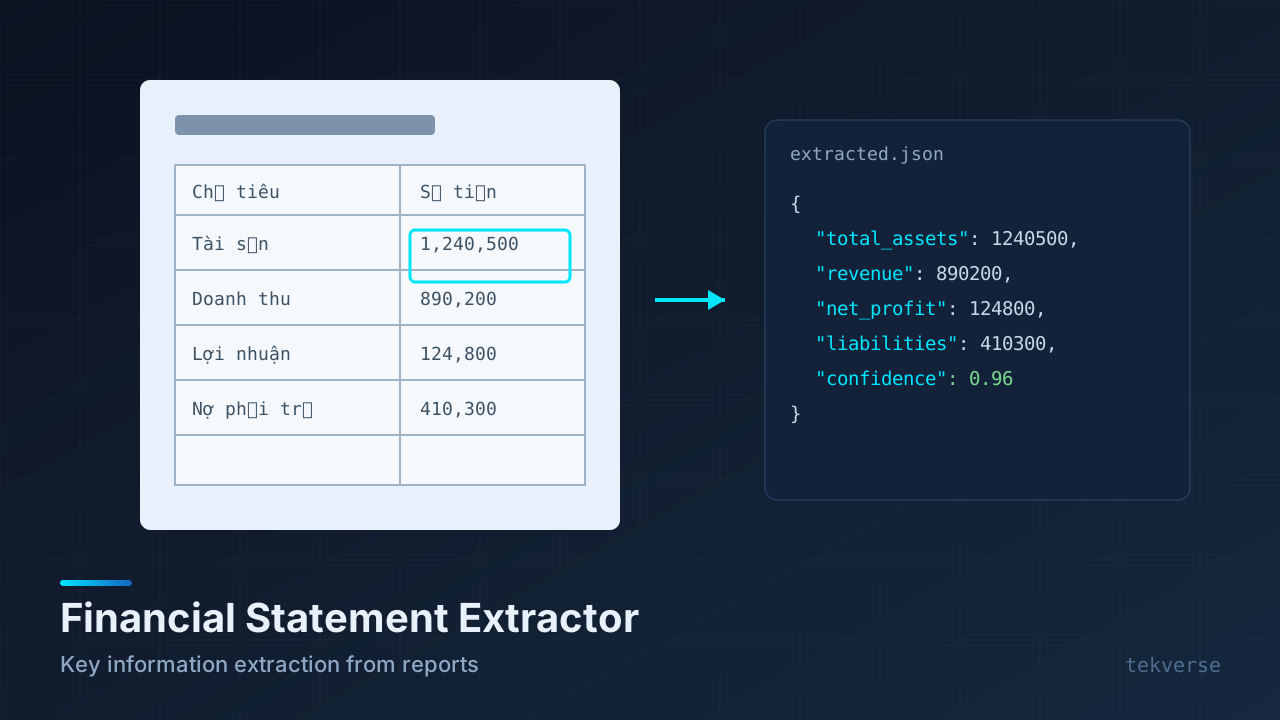
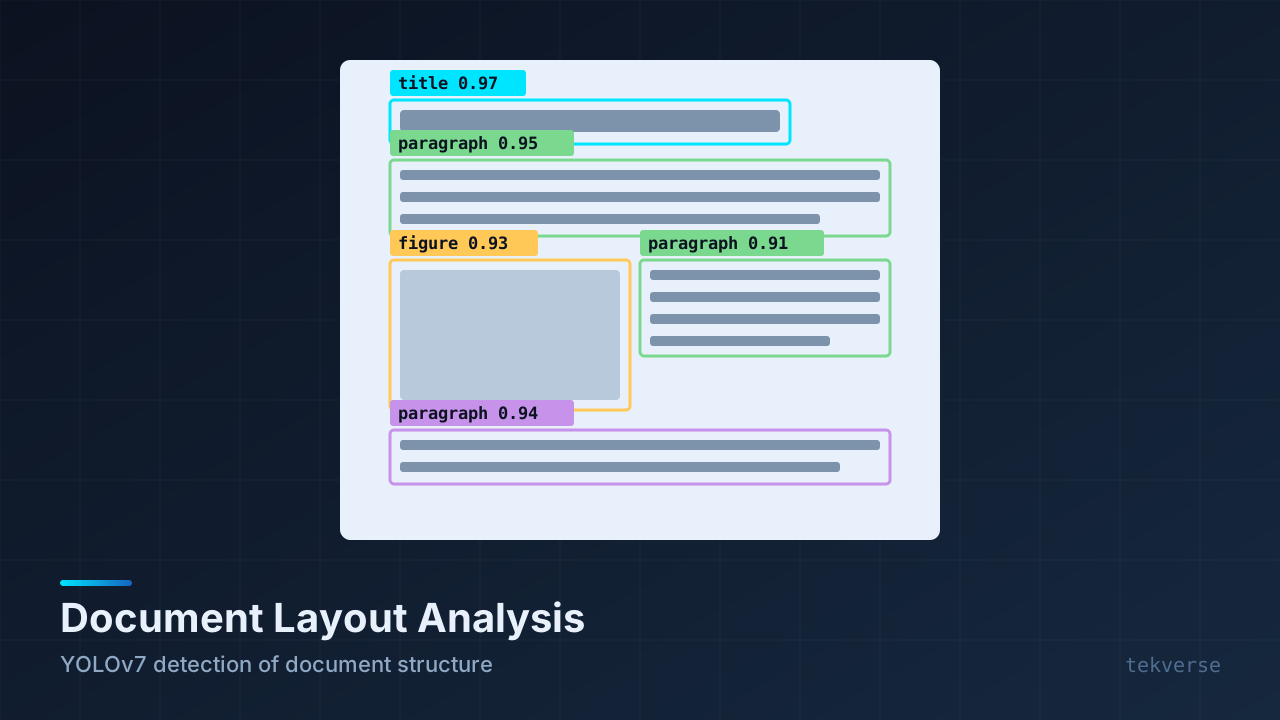
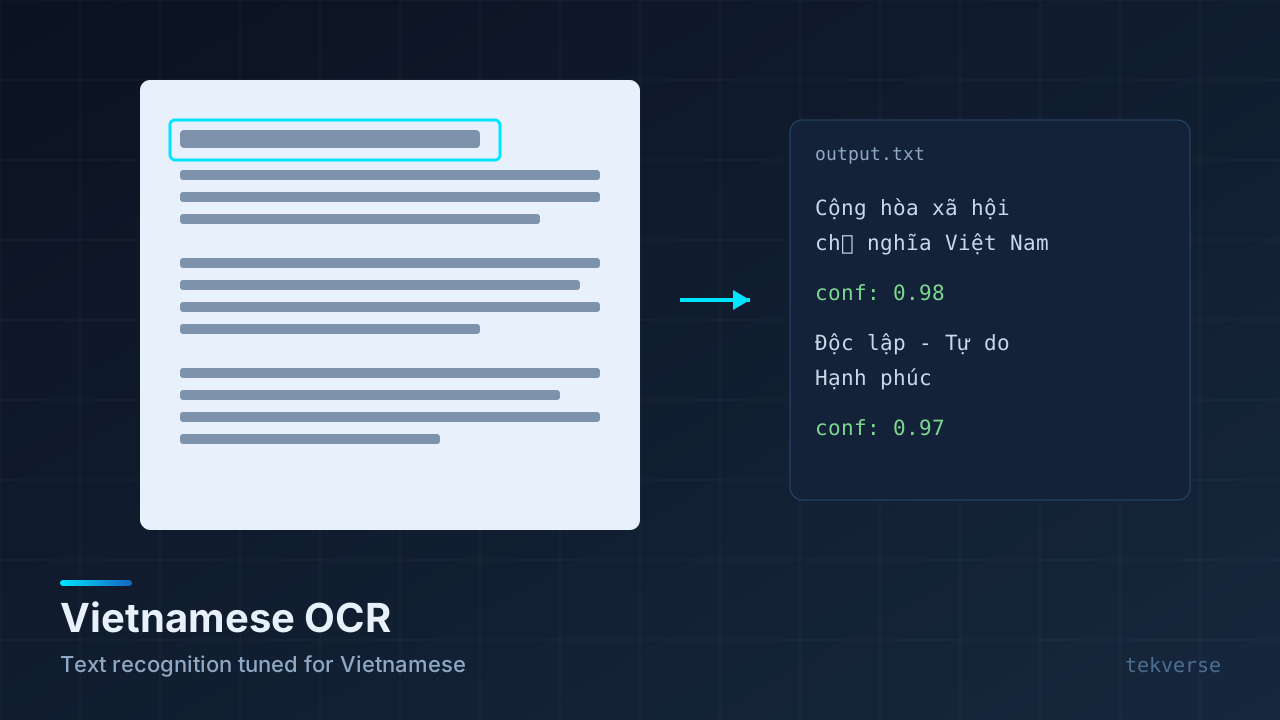
Built on our open-source work in Vietnamese OCR and document layout analysis, we digitize documents end-to-end: detect layout, read Vietnamese text accurately, and extract key fields from financial statements, invoices, and forms into clean structured data.

Banking & FinanceEnterprise

Interactive demo

Document AI

Vietnamese OCR

Pick a sample document and run the pipeline: layout analysis, text recognition, then structured extraction.

Ký hiệu: 1C26TAA · Số: 0000123
HÓA ĐƠN GIÁ TRỊ GIA TĂNG
Ngày 12 tháng 10 năm 2026
Đơn vị bán hàng: CÔNG TY CỔ PHẦN MẪU A
Mã số thuế: 0123456789 · Địa chỉ: Số 1 Đường Mẫu, Quận Mẫu, TP. Mẫu
Đơn vị mua hàng: CÔNG TY TNHH KHÁCH HÀNG B
Mã số thuế: 0312345678 · Địa chỉ: Số 2 Đường Mẫu, Quận Mẫu, TP. Mẫu
STTTên hàng hóa, dịch vụĐVTSLĐơn giáThành tiền
1Bản quyền phần mềm nhận dạng OCRGói150.000.00050.000.000
2Tư vấn triển khai hạ tầng cloudTháng215.000.00030.000.000
3Bảo trì hệ thống máy chủNăm112.000.00012.000.000
4Đào tạo sử dụng hệ thống AIGói18.000.0008.000.000
Cộng tiền hàng: 100.000.000
Thuế suất GTGT: 10% · Tiền thuế GTGT: 10.000.000
Tổng cộng tiền thanh toán: 110.000.000
Số tiền bằng chữ: Một trăm mười triệu đồng chẵn.
SAMPLE

Press Run OCR to see the recognised text.

Simulated with sample documents (organisations, IDs and signatures are placeholders). The structured extraction is computed directly from the recognised lines. The real pipeline runs YOLOv7 layout analysis + VietOCR recognition.

Technical capabilities

01

Vietnamese OCR

High-accuracy Vietnamese text recognition, robust to fonts, scans, and photos.

02

Layout Analysis

AI-based detection of titles, paragraphs, tables, and figures to understand document structure.

03

Financial Document Extraction

Key-information extraction from financial statements and reports into analysis-ready datasets.

04

Table Extraction

Reconstruct tables from scans into spreadsheets and databases while preserving structure.

05

PDF & Scan Pipeline

Batch processing pipelines for large archives: deskew, denoise, OCR, extract, and index.

06

LLM-assisted Understanding

Combine OCR with LLMs to classify documents, resolve ambiguity, and validate extracted fields.

Processing pipeline

01

Scan / PDF

Input

02

Layout Analysis

YOLOv7

03

OCR

VietOCR / TrOCR

04

Extraction

NLP / LLM

05

Structured Data

JSON / DB

Deployment scenarios

Banking & Finance

Financial Statement Digitization

Automatically extract balance-sheet and income-statement figures from scanned reports for credit analysis and data platforms.

  • Key financial figure extraction
  • Table structure reconstruction
  • Validation rules and confidence scoring
KIETablesFinance
Business Operations

Invoice & Form Automation

Cut manual data entry: invoices, contracts, and forms are read, validated, and pushed into ERP/accounting systems.

  • Invoice field extraction (VAT, totals, parties)
  • ERP/accounting integration via API
  • Human-in-the-loop review UI
InvoicesERPAutomation
Archives

Large-scale Archive Digitization

Turn decades of paper archives into a searchable digital library with full-text OCR and metadata extraction.

  • Batch scanning pipeline with QA
  • Full-text search index
  • Automatic document classification
Full-text SearchClassificationBatch

Tech stack

VietOCRTrOCRYOLOv7PaddleOCROpenCVTransformersPyTorchFastAPI

Related projects