← All projects
AI servicesRUNNING
Document Layout Analysis (YOLOv7)
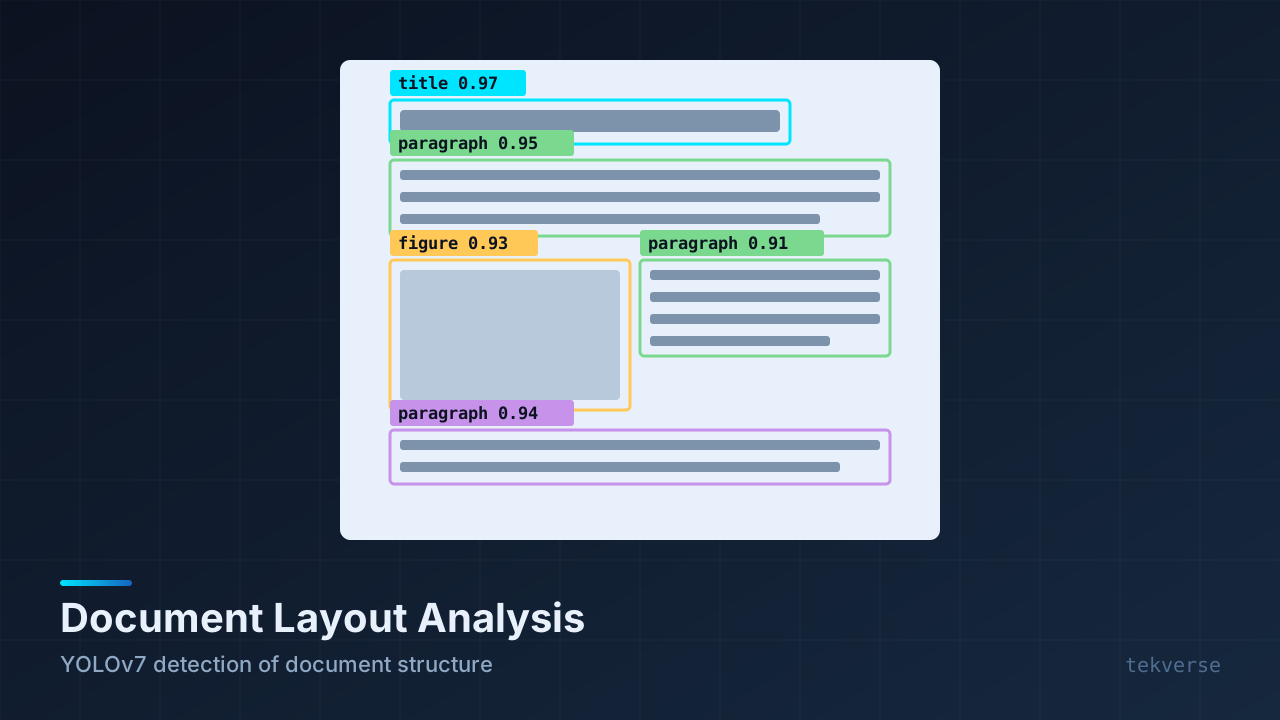
YOLOv7-based detection of titles, paragraphs, tables, and figures for document understanding pipelines
Overview
Document Layout Analysis applies the YOLOv7 object detector to document pages, locating structural elements - titles, paragraphs, tables, figures, and captions - before OCR and extraction. Understanding layout first dramatically improves downstream OCR accuracy and enables structure-aware extraction, making it a key building block of our Document AI stack.
Key features
Detects titles, paragraphs, tables, figures
Improves downstream OCR accuracy
Structure-aware extraction support
Open source on GitHub
Tech stack
YOLOv7 · aiPyTorch · aiOpenCV · aiPython · backend