Vietnamese OCR
Open-source optical character recognition pipeline tuned for Vietnamese text in scanned documents and photos
Overview
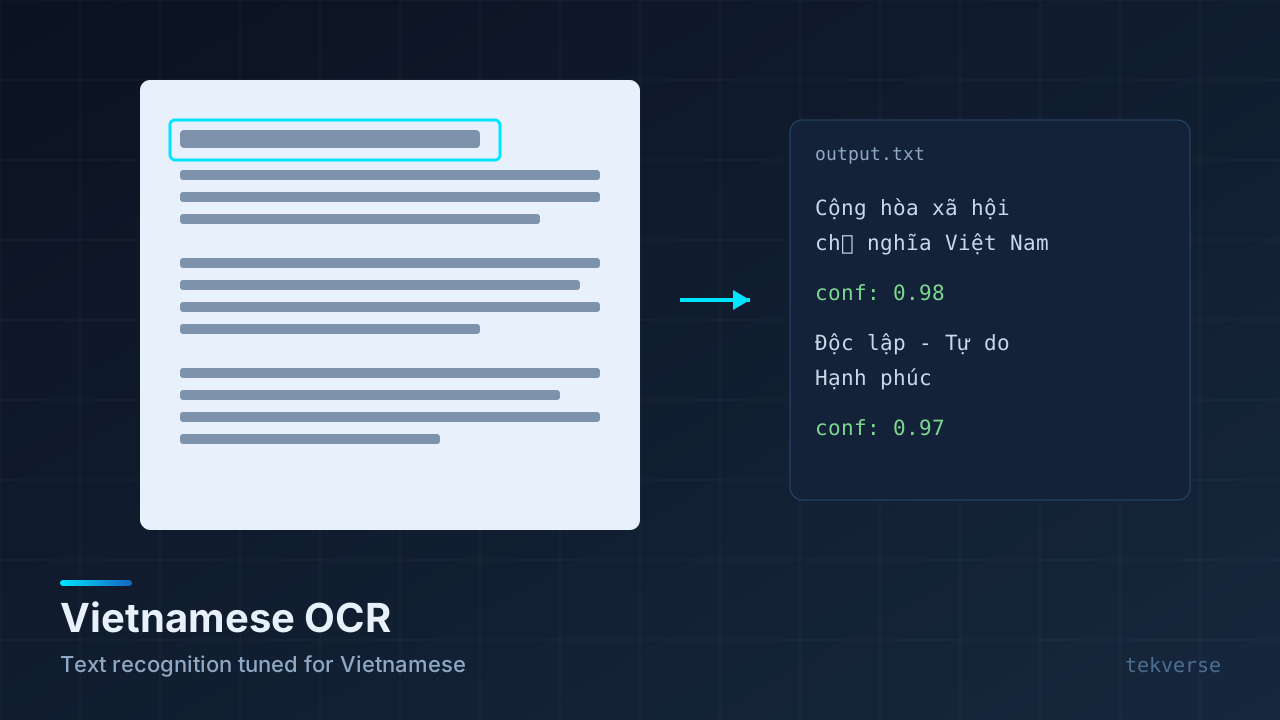
Vietnamese OCR is our open-source text recognition pipeline built specifically for the Vietnamese language, handling its diacritics and typography accurately across scanned documents, photos, and mixed layouts. It combines text detection with transformer-based recognition models, and serves as the OCR engine behind our Document AI solutions - from financial statement extraction to archive digitization.
Interactive demo
Vietnamese OCR
Pick a sample document and run the pipeline: layout analysis, text recognition, then structured extraction.
Press Run OCR to see the recognised text.
Simulated with sample documents (organisations, IDs and signatures are placeholders). The structured extraction is computed directly from the recognised lines. The real pipeline runs YOLOv7 layout analysis + VietOCR recognition.