Vectiq AIaaS - GPU Cloud & MLOps as a Service
A multi-tenant GPU cloud in development: each customer gets an isolated namespace, queued GPU training, LoRA fine-tuning, Triton serving and billing by GPU hour
Overview
Vectiq AIaaS is the service we are building to rent GPU capacity together with the MLOps tooling around it, so a customer can train, fine-tune and serve larger models without running a cluster.
Creating a tenant provisions a Kubernetes namespace with RBAC and a NetworkPolicy, a storage volume, an object-storage bucket, an identity in Keycloak and a place in the Kueue GPU queue, and rolls these back if a step fails; tenants currently share one queue, and per-tenant GPU quotas are in development.
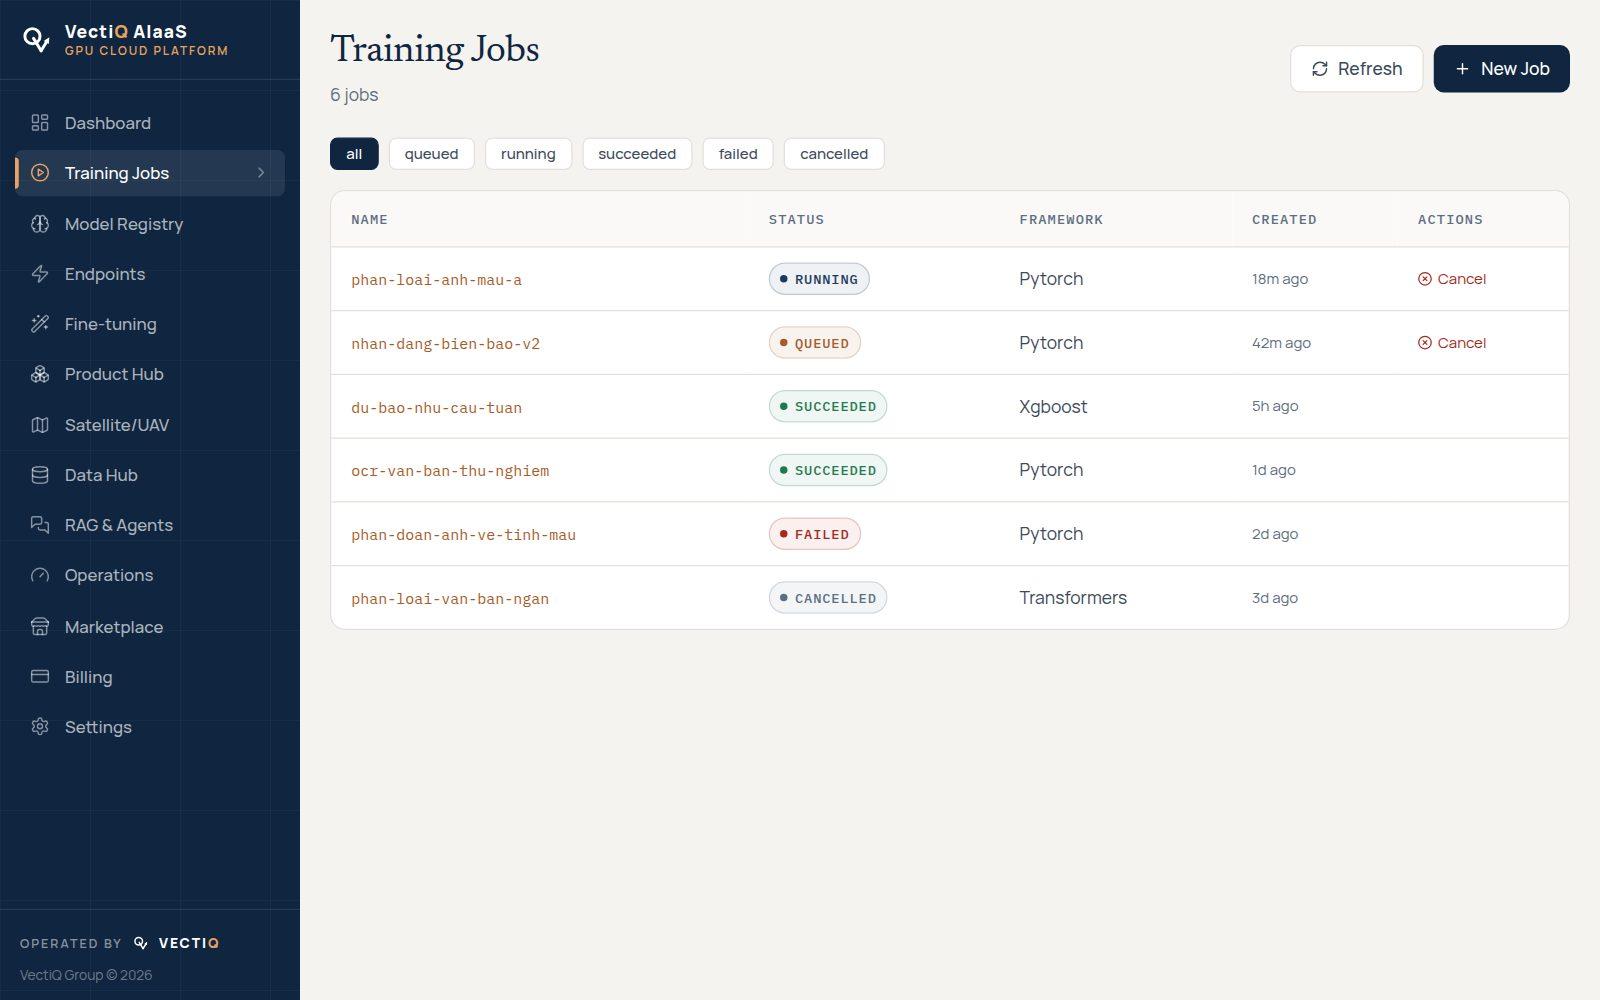
Training jobs are submitted as Kubernetes Jobs that can ask for a whole GPU or an A100 MIG slice; fine-tuning jobs carry LoRA/QLoRA settings; trained models are copied into a Triton model repository and served from a per-tenant deployment.
The model registry checks artifacts, a smoke test against Triton and performance against the current production version before promotion, and the billing service meters GPU hours, inference and storage into invoices. The eight services and the portal run together in a local environment; the platform has not yet been deployed on a GPU cluster, which is why it is listed as coming soon.